Meta’s spare GPUs expose the real cost of keeping AI training running
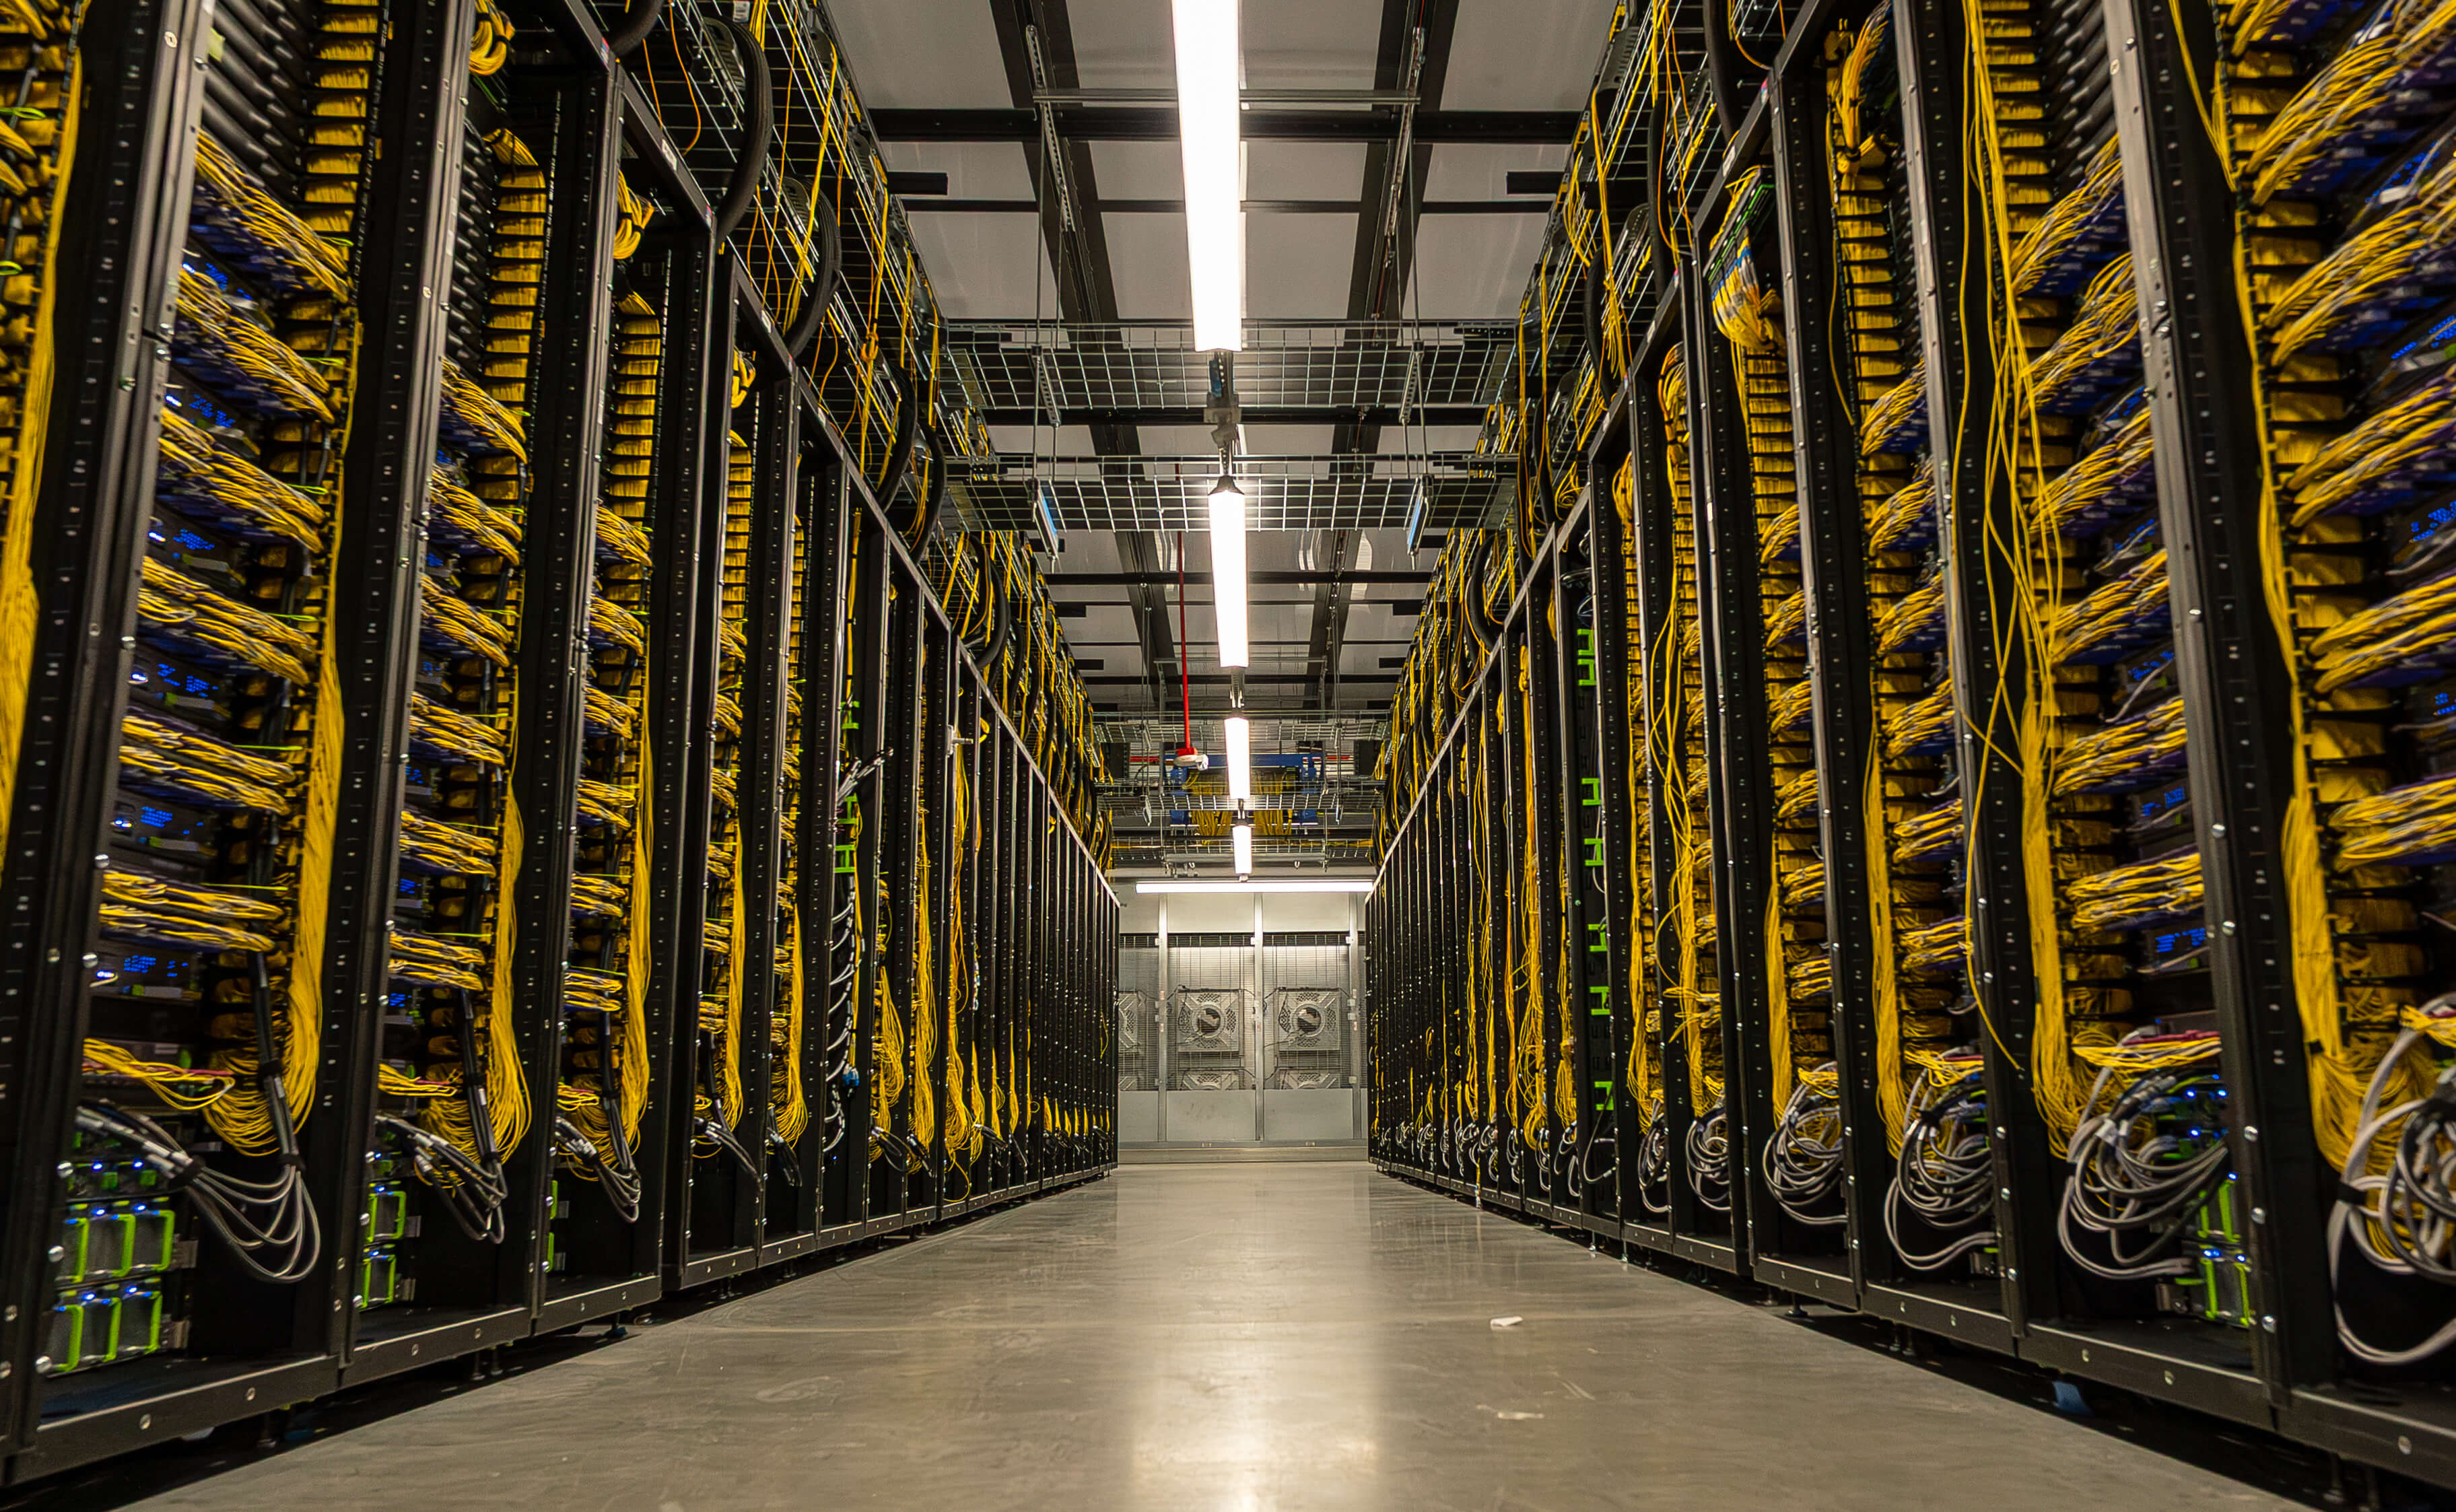
Image: Meta
A training job that needs 32,768 GPUs can require the purchase of considerably more than 32,768 GPUs. In Meta’s Prometheus example, the provisioned total is 37,656. The gap is large enough to make a respectable cluster of its own.
Meta allocates 64 working GPUs within each 72-GPU NVLink domain, keeping eight available as spares. It also reserves additional racks against larger failures. The arrangement accommodates power-of-two training groups while providing replacement hardware close to the failed device. A defective GPU can be exchanged in the job without waiting for a technician to repair it.
On those published counts, 4,888 GPUs sit outside the active training footprint, roughly 15% of the active total. That arithmetic is a useful antidote to treating every installed accelerator as an accelerator continuously doing useful work. Some capacity buys resilience; some follows from the geometry of fitting the workload to the machine.
The decision looks different when the cost of an interruption is included. Replacing a component is only one task. A distributed job must also recover its state, restore communication and resume computation. If the whole job pauses, healthy processors spend that interval waiting too. The economic value of a spare therefore depends partly on how much other hardware it keeps productive.
Meta reports pre-training goodput above 85% for its Muse Wonder runs. Its account describes both local recovery, where an affected replica is restarted while others continue, and recovery from checkpoints for wider failures. These are the operator’s results, rather than a universal performance figure for an NVL72 installation.
There is another form of unusable capacity below the racks, in the electrical distribution system. In a separate study of a 100MW-scale cluster, Meta researchers found that uneven loading could strand 5–10% of available power. Some main switchboards retained headroom while others approached their limits. The constrained section governed how aggressively the cluster could raise GPU power.
An average across the site conceals that difference. Spare electrical capacity on one distribution branch cannot simply be assigned to a rack supplied by another. The researchers describe moving supporting service racks to relieve the tightest sections, while relocating compute racks would involve extensive fibre work and disruption.
Moving a workload between processors does not move the electrical connection supplying them. Relieving a constrained switchboard can require a physical change to the installation, with the service-rack moves described by the researchers offering one route that avoids relocating the compute racks themselves.